Introduction The landscape of terminal-based AI agents has undergone substantial transformation recently, particularly affecting developers in the fields of Computer Vision and Image Processing. These changes necessitate a deeper understanding of the tools available for managing and optimizing workflows, especially as the technologies powering these agents evolve. Notably, the transition from Google’s Gemini CLI to Antigravity CLI represents a pivotal shift that merits careful consideration for practitioners relying on these technologies. Context and Significance The retirement of Gemini CLI, a tool that has served as an essential resource for many developers, underscores the importance of adaptability within the technological ecosystem. The introduction of Antigravity CLI, while offering advanced features, raises concerns regarding its closed-source nature, which contrasts sharply with the open-source ethos that characterized its predecessor. Such transitions can significantly affect existing scripts and CI/CD pipelines, making it imperative for developers to reassess their tools and workflows. Main Goals and Achievements The primary goal of understanding these shifts in AI CLI tools is to ensure that developers can maintain efficient and effective workflows while leveraging the latest advancements in technology. This can be achieved by: Assessing the implications of transitioning to Antigravity CLI and its effects on existing systems. Exploring new features in Claude Code, particularly its enhanced context window and Dynamic Workflows, to improve task automation. Examining the architecture of OpenClaw, including its extensibility and security considerations, to maximize its potential in real-world applications. Advantages and Limitations Several key advantages arise from the recent developments in AI CLI tools: Enhanced Functionality: Claude Code’s Opus 4.8 and Fable 5 models offer a 1M-token context window, greatly facilitating the handling of larger datasets typical in Computer Vision tasks. Open Source Opportunities: OpenClaw’s growth within the GitHub community illustrates the collaborative potential of open-source software, allowing Vision Scientists to contribute to and benefit from shared developments. Dynamic Workflows: The introduction of Dynamic Workflows in Claude Code streamlines processes, thus optimizing productivity for developers engaged in complex image processing tasks. However, it is essential to note certain limitations: Transition Challenges: The move from Gemini CLI to Antigravity CLI may disrupt existing workflows, requiring developers to invest time in adapting or rewriting scripts. Security Concerns: Antigravity CLI’s closed-source nature introduces potential vulnerabilities that must be carefully managed, particularly given the sensitive data often processed in the field of Computer Vision. Future Implications The advancements in AI CLI tools signal a broader trend toward the integration of AI in various domains, particularly in Computer Vision and Image Processing. As these tools become more sophisticated, they will likely facilitate increased automation and efficiency in data handling and analysis. This evolution is poised to empower Vision Scientists to deploy more complex models and algorithms, ultimately leading to breakthroughs in image recognition, object detection, and beyond. Moreover, the ongoing development of both proprietary and open-source tools will continue to shape the landscape, fostering a competitive environment that incentivizes innovation. As AI technologies advance, it is crucial for professionals in the field to remain agile and informed, ensuring that they leverage these tools to their fullest potential. Conclusion In summary, the evolving AI CLI landscape presents both challenges and opportunities for developers in the Computer Vision and Image Processing sectors. Understanding the implications of these changes is vital for optimizing workflows and harnessing the full power of emerging technologies. By staying informed and adaptable, Vision Scientists can navigate these transitions effectively, paving the way for future advancements in their field. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here
Context In the realm of software development, managing sensitive information, often referred to as “secrets,” is crucial for maintaining security and integrity. GitHub’s initiative to enhance secrets hygiene serves as a compelling case study, illustrating the challenges faced by organizations in safeguarding their data. Over a period of nine months, GitHub successfully identified and mitigated over 20,000 alerts related to potential secrets across its vast repository landscape, culminating in a state of zero open alerts. This endeavor not only reflects a commitment to security but also offers valuable insights for organizations, especially in the Big Data Engineering sector, where the abundance of data necessitates stringent measures for data protection. Main Goal and Achievements The primary goal of GitHub’s secret scanning initiative was to enhance the security posture by effectively identifying and remediating secrets within their codebase. This objective was achieved through a systematic approach that encompassed several phases: stopping the accumulation of new secrets, understanding and triaging existing alerts, validating the status of credentials, and driving accountability through ownership. By implementing these strategies, GitHub not only reached operational efficiency but also fostered a culture of security awareness among its teams. Advantages of Effective Secrets Management Reduction of Security Risks: By identifying and remediating potential secrets, organizations can significantly mitigate the risk of unauthorized access to sensitive information. GitHub’s approach demonstrated that a significant majority of alerts could be categorized as low-risk, allowing for focused remediation efforts. Improved Operational Efficiency: The phased approach adopted by GitHub facilitated a systematic resolution of alerts, enhancing operational workflows. By automating certain processes and employing bulk closure strategies, GitHub was able to manage a high volume of alerts without overwhelming their security teams. Enhanced Collaboration: The initiative required cross-functional collaboration among various teams, including customer support and security incident response. This not only improved the effectiveness of the remediation process but also fostered a culture of collective responsibility for security across the organization. Data-Driven Decision Making: The ability to validate the status of credentials allowed GitHub to prioritize remediation efforts effectively. By differentiating between live and inactive credentials, the organization could focus on high-risk areas, thereby optimizing resource allocation. Caveats and Limitations While the advantages of effective secrets management are evident, certain limitations must be acknowledged. The initial count of alerts can be misleading, as demonstrated by GitHub’s experience where the majority of alerts were inactive. Additionally, the implementation of such a comprehensive approach requires significant organizational commitment and resources. Organizations must also consider the potential for operational disruptions when rewriting git history or altering existing repositories. Future Implications Looking ahead, the integration of artificial intelligence (AI) into secrets management processes is poised to revolutionize the field. AI can enhance the accuracy of alerts by employing machine learning algorithms to identify patterns and anomalies in code. Furthermore, AI-driven tools can automate the remediation process, reducing the need for manual intervention and minimizing human error. As organizations continue to grapple with the complexities of data security in an increasingly digital landscape, leveraging AI technologies will be essential for maintaining robust security practices. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here
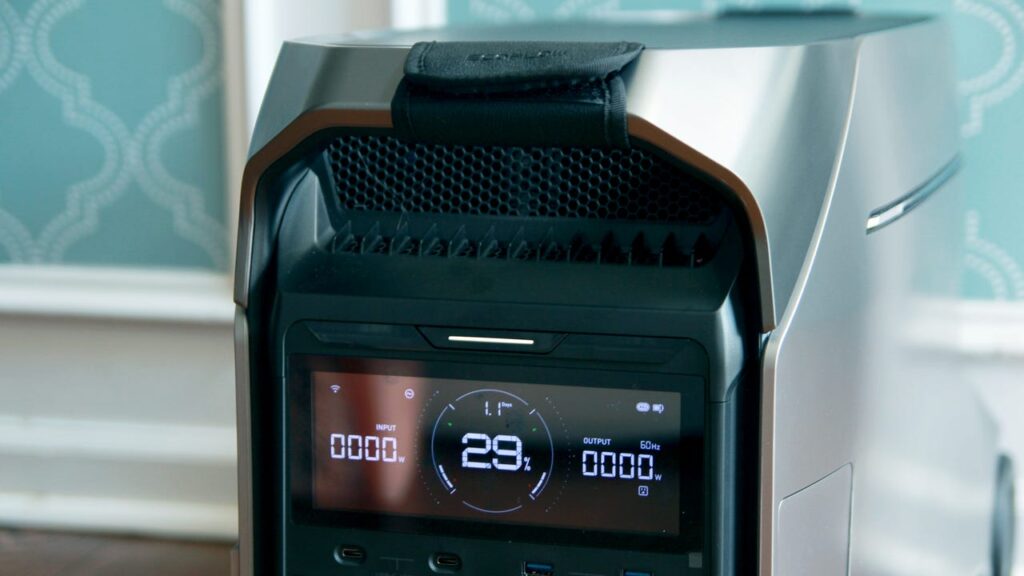
Contextualizing Power Station Usage in Applied Machine Learning In recent years, the proliferation of smart devices and the emphasis on uninterrupted power supply have gained significant traction in various fields, including Applied Machine Learning (AML). The original blog post highlights the importance of maintaining continuous power to essential devices, such as modems, routers, refrigerators, and security cameras, particularly during power outages. For AML practitioners, the reliability of power sources directly impacts their ability to conduct research, manage data pipelines, and ensure the seamless operation of machine learning models. This discussion underscores the necessity of integrating uninterruptible power supplies (UPS) to mitigate risks associated with unexpected power disruptions. Main Goal of Power Station Utilization The primary objective of keeping specific devices connected to a power station is to maintain functionality during power outages. This is particularly critical for individuals who rely on technology for both professional and personal purposes. By utilizing UPS systems, practitioners can ensure that their essential devices remain operational, thereby enhancing productivity and safeguarding valuable data. Advantages of Utilizing Power Stations Continuous Connectivity: Maintaining power to modems and routers ensures uninterrupted internet access, which is crucial for remote work and data management tasks. Without connectivity, AML practitioners may face challenges in model training and performance evaluation. Data Integrity: By keeping devices such as refrigerators operational, practitioners can ensure that data related to environmental conditions or data collection remain viable, preventing data loss or degradation. Enhanced Security: Continuous power to security systems allows for the ongoing monitoring of premises, ensuring the safety of physical infrastructure that houses sensitive data or hardware used in AML projects. Caveats and Limitations While the advantages of utilizing power stations are substantial, several factors must be considered. The capacity of the power station must align with the energy requirements of the connected devices. For instance, not all power stations can accommodate high-demand appliances or multiple devices simultaneously. Additionally, reliance on a UPS may provide a false sense of security if practitioners do not regularly test and maintain their systems, potentially leading to failures during critical moments. Future Implications of AI Developments The rapid advancement of AI will continue to influence the need for reliable power sources in AML. As machine learning models become increasingly complex and data-intensive, the demand for consistent power supply will surge. Future AI developments may lead to the integration of intelligent power management systems capable of dynamically allocating resources based on current demand, further enhancing the resilience of machine learning infrastructures. Additionally, as the Internet of Things (IoT) expands, the reliance on connected devices will necessitate robust power solutions, making UPS systems even more critical for practitioners in the field. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here
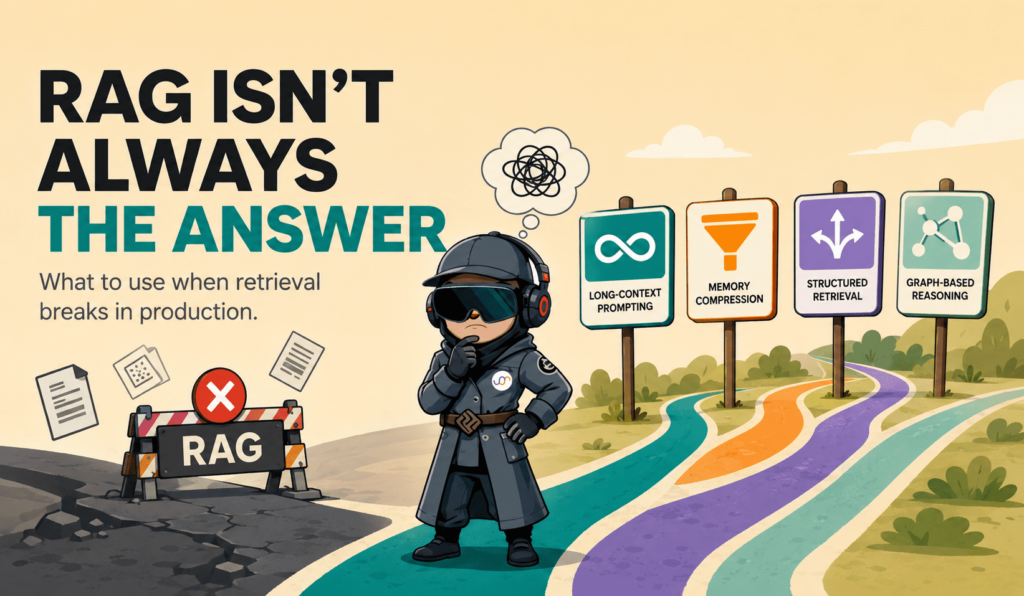
Introduction Retrieval-augmented generation (RAG) has emerged as a prominent methodology for augmenting the capabilities of large language models (LLMs) by effectively linking them to a corpus of documents. This integration involves a straightforward procedure: embedding a corpus, retrieving relevant segments via vector similarity, and incorporating them into model prompts. While this framework shows promise in practical applications, it often falters under the pressures of real-world deployment, revealing failure modes that are not apparent during initial demonstrations. Understanding these limitations and exploring alternative approaches is paramount for optimizing the efficacy of LLMs in natural language understanding (NLU). When RAG Fails in Production In practical applications, one of the most frequently encountered issues with RAG systems is retrieval irrelevance. For instance, when a user inquires about a parental leave policy, the system may return multiple outdated or off-topic documents that superficially align with the query based on shared vocabulary but fail to provide the necessary context. This results in the model generating responses that are confidently articulated yet factually incorrect, highlighting a critical distinction between topical similarity and factual relevance. Another insidious challenge is context poisoning, which arises in enterprise knowledge bases where multiple versions of the same document exist. When a retrieval system draws from these conflicting sources, the model amalgamates the information without recognizing inherent contradictions, again producing misleading outputs. These scenarios underscore the fundamental structural conflicts within the chunk-embed-retrieve pipeline that complicate the balance between recall and coherence. The Common (Wrong) Fix: Over-Engineering In response to the shortcomings of standard RAG systems, a prevalent but misguided approach is to introduce complexity through higher-dimensional embeddings and advanced reranking strategies. This over-engineering often exacerbates existing issues rather than resolving them. For example, a global manufacturing corporation initially budgeted $400K for its RAG implementation but incurred costs of $1.2M in the first year, achieving only a 23% accuracy rate on technical documentation queries. Such experiences reflect a broader trend of failure in enterprise RAG implementations, with a staggering 72% failure rate reported in the first year of operation. Increasing the sophistication of vector models does not guarantee improved performance; it often leads to heightened computational expenses and diverts attention from the more critical question of whether the initial retrieval architecture was appropriate. Alternatives When RAG Fails Long-Context Prompting A practical alternative to circumvent the complexities of a malfunctioning RAG pipeline is to adopt long-context prompting. This strategy eliminates the retrieval step entirely by loading the entire corpus directly into the model, provided it fits within the model’s context window. Research has indicated that long-context models can consistently outperform traditional RAG on question-answering tasks when computational resources permit, albeit at a significantly higher cost in terms of latency and per-query expenses. Memory Compression When the corpus exceeds the context window, an effective strategy is to utilize summarization before retrieval. This approach involves compressing documents prior to their integration into the model, which can yield performance comparable to long-context methods while avoiding the pitfalls of raw chunk retrieval. Evidence suggests that well-compressed relevant documents can outperform larger sets of tangentially related chunks. Structured Retrieval In instances where retrieval remains a viable architecture, implementing structured retrieval can enhance accuracy and reduce computational costs. By classifying queries based on their type—whether they require full context or focused retrieval—systems can optimize their responses accordingly. Recent studies demonstrate that adaptive systems employing this hybrid approach have achieved significant improvements in retrieval precision, thereby validating the efficacy of explicit routing in enhancing overall system performance. Graph-Based Reasoning For queries that necessitate an understanding of relationships across datasets, traditional vector retrieval methods fall short. Multi-hop questions, which require synthesis of information across various documents, benefit from graph-based reasoning techniques. Microsoft Research has introduced systems that construct knowledge graphs from the corpus, enabling the exploration of entity relationships rather than mere vector matching. While this method incurs higher costs, it is particularly advantageous for thematic analysis and multi-hop reasoning, albeit less effective for straightforward factual lookups. Conclusion While RAG serves as a reasonable default for many applications, its limitations become apparent in predictable ways, such as retrieval irrelevance and context poisoning. Adding complexity to an already flawed design often results in increased expenses without resolving the core issues. By aligning the architectural choices with the nature of the queries, practitioners can enhance both performance and efficiency. The four outlined alternatives—long-context prompting, memory compression, structured retrieval, and graph-based reasoning—offer distinct pathways to improve the functionality of NLU systems, ultimately paving the way for more robust and reliable AI applications in the future. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here
Context: The Significance of the Rousseeuw Prize in Data Analytics The Rousseeuw Prize for Statistics serves as a hallmark of excellence in the field of statistics, recognizing significant contributions made by individuals and teams who advance statistical methodologies and applications. Recently, this prestigious award was presented to the R Core Team, which includes notable figures such as Brian Ripley, Martin Mächler, Kurt Hornik, Peter Dalgaard, and Luke Tierney. The R programming language has become a cornerstone of modern statistical computing, driven by a commitment to open-source principles and community collaboration. As the R community prepares to launch version 4.6.1, it underscores the continuous evolution and impact of this tool within the analytics landscape. Main Goal: Recognition of Contributions to Statistical Research The primary objective of the Rousseeuw Prize is to acknowledge the groundbreaking efforts of statisticians who have dedicated their careers to enhancing statistical tools and methodologies. Achieving this goal involves fostering an environment that promotes innovation, collaboration, and open access to statistical resources. By recognizing these contributions, the prize not only celebrates individual achievements but also inspires future generations of statisticians and data engineers to pursue excellence in their work. Advantages of the Rousseeuw Prize for Data Engineers Validation of Open-Source Contributions: The award highlights the importance of open-source projects like R in advancing statistical knowledge, providing data engineers with a robust framework that they can leverage for their analytics tasks. Encouragement of Community Engagement: By recognizing collaborative efforts within the R community, the prize encourages data engineers to participate in open-source projects, thereby enhancing their skills through shared knowledge and experience. Enhanced Trust in Statistical Tools: The acknowledgment of the R Core Team’s work reinforces the credibility of R as a statistical tool, encouraging data engineers to adopt it for critical projects, especially in regulated industries such as pharmaceuticals and finance. Inspiration for Innovation: The recognition of significant contributions serves as a motivational factor, prompting data engineers to innovate and experiment with new methodologies, thus advancing the field of data analytics. Future Implications: The Role of AI in Data Analytics The ongoing expansion of artificial intelligence (AI) technologies is poised to further transform the landscape of data analytics. As AI methodologies increasingly intersect with statistical practices, data engineers will need to adapt to new paradigms of data interpretation and analysis. Tools like R will continue to evolve, incorporating AI capabilities that enable more sophisticated data modeling and predictive analytics. This evolution will not only refine existing statistical techniques but also broaden the scope of analytics applications across various industries, enabling data engineers to derive deeper insights from complex datasets. Conclusion The Rousseeuw Prize for Statistics embodies the commitment to excellence and innovation within the field of statistics, particularly through the contributions of the R Core Team. For data engineers, the recognition of such contributions not only validates their work but also provides a framework for future advancements in data analytics. As the integration of AI technologies continues to shape the industry, data engineers are positioned to leverage these developments to enhance their analytical capabilities and drive meaningful insights. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here
Contextualizing the Need for a Web Data Infrastructure Layer in AI The evolution of artificial intelligence (AI) is increasingly reliant on a robust web data infrastructure layer. This layer serves as a critical component, enabling AI models to effectively navigate an extensive digital landscape characterized by millions of existing web domains and billions of new URLs created weekly. As the volume of available data expands, the necessity for a framework that can deliver real-time information and surmount existing technical barriers becomes paramount. Or Lenchner, CEO of Bright Data, aptly notes that the sheer volume of uncharted data necessitates enhanced discovery mechanisms, akin to exploring a vast universe where much remains unknown. Main Goal: Achieving Real-Time, Trustworthy Data Access The primary goal of establishing this web data infrastructure layer is to facilitate access to fresh, relevant, and trustworthy data. While early advancements in AI were primarily focused on scaling training datasets and increasing model complexity, organizations now face a significant challenge: the need to remain aligned with the dynamic, unstructured, and constantly evolving nature of web data. This alignment is crucial for grounding AI outputs in current and verifiable information, thereby enhancing overall model performance. To achieve this goal, organizations must invest in advanced systems that integrate compute, networking, retrieval, and data engineering capabilities. These systems must be adept at quickly retrieving data that meets the criteria of freshness, relevance, and trustworthiness. Advantages of a Robust Web Data Infrastructure Layer Real-Time Data Retrieval: The ability to access real-time data ensures that AI models are informed by the most current information, thereby reducing the risk of outdated or irrelevant outputs. This is essential for businesses that must adapt swiftly to changes in consumer sentiment, market trends, and competitive pricing. Enhanced Decision-Making: AI systems equipped with fresh data can provide contextually relevant insights, which are vital for informed decision-making. In business environments, reliance on stale data can lead to poor choices, ultimately affecting customer satisfaction and business performance. Reduced AI Hallucinations: Access to high-quality web data minimizes the occurrence of AI hallucinations, where models generate outputs that are not grounded in reality. A more relevant knowledge base fosters user trust, as evidenced by a survey indicating that 56% of AI practitioners believe real-time web data access is critical for enhancing confidence in AI outputs. Scalability and Efficiency: A comprehensive web data infrastructure can handle millions of concurrent interactions across diverse websites, accommodating variations in geography, language, format, and access rules. This scalability is essential for organizations aiming to leverage AI in a global marketplace. Limitations and Considerations While the advantages of a web data infrastructure layer are compelling, organizations must also navigate certain limitations. The implementation of such systems can incur significant costs and require substantial training and adaptation. Furthermore, despite advancements in techniques such as retrieval-augmented generation (RAG), many AI models continue to struggle with delivering timely and contextually appropriate outputs. According to Gartner, 60% of AI projects that lack AI-ready data—characterized by accuracy, structure, organization, and contextuality—are likely to be abandoned by the year’s end. Future Implications of AI Developments As AI technology continues to advance, the importance of an effective web data infrastructure layer will only heighten. The ongoing integration of AI into various sectors will necessitate increasingly sophisticated methods for data retrieval and processing. Future developments may lead to enhanced machine learning models capable of autonomously navigating data landscapes, thereby further reducing the reliance on static datasets. However, organizations must remain vigilant in their approach to data governance, ensuring that data used is not only timely and relevant but also ethically sourced and compliant with regulations. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here
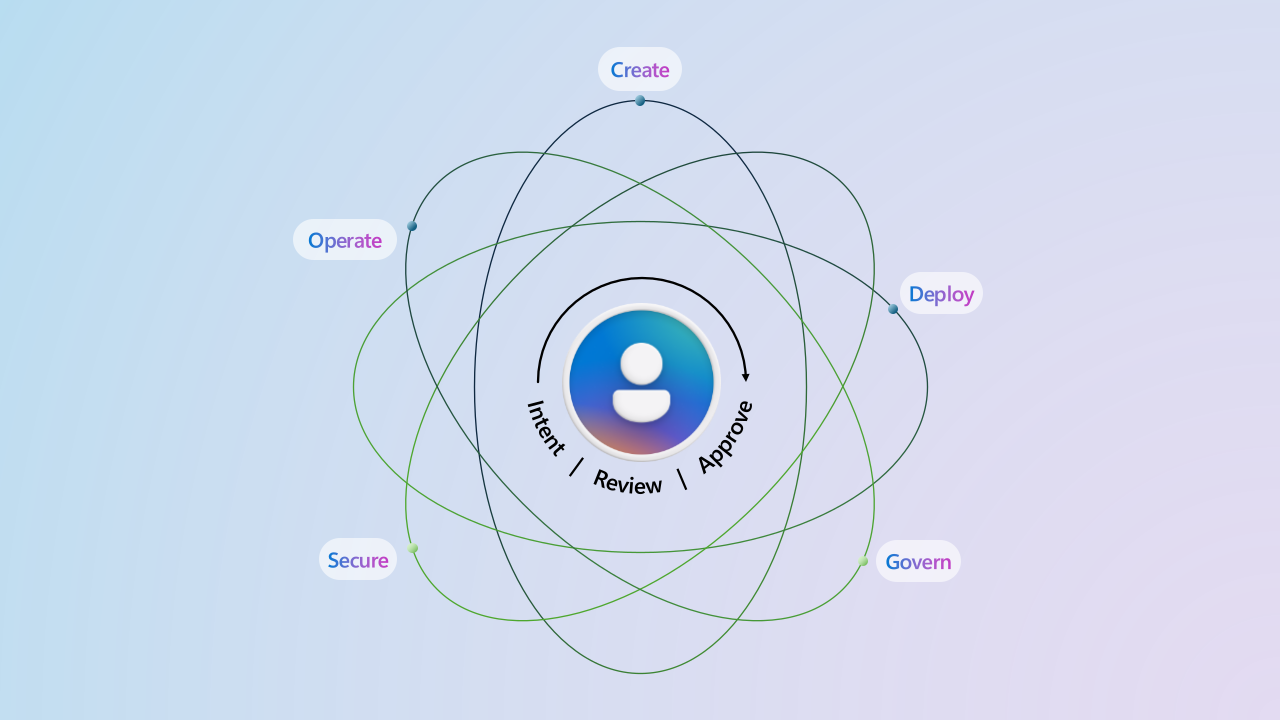
Contextualizing Agentic Cloud Operations in Big Data Engineering The transition from insight to action in cloud environments represents a pivotal evolution in the realm of Big Data Engineering. As organizations increasingly rely on complex hybrid infrastructures, microservices, and artificial intelligence (AI) workloads, the need for an operational model that seamlessly integrates insight and action becomes imperative. The concept of agentic cloud operations emerges as a solution that employs AI-powered agents, which continuously observe and reason through the cloud lifecycle, transforming isolated signals into actionable workflows. This systematic approach not only enhances performance and reduces costs but also fortifies reliability across data operations. Main Goal of Agentic Cloud Operations The core objective of agentic cloud operations is to create an environment where insights derived from data are directly translated into actions in real-time. This model facilitates a dynamic feedback loop, allowing organizations to respond to changing conditions and requirements promptly. Achieving this goal necessitates embedding governance within cloud operations, ensuring that every action adheres to predefined policies and organizational intent. By implementing this model, organizations can ensure that their cloud environments operate efficiently and effectively, ultimately leading to optimized performance and decision-making. Advantages of Agentic Cloud Operations Enhanced Governance: The integration of governance into cloud operations ensures that actions taken by AI agents are auditable and repeatable, aligning with organizational policies. This is crucial for compliance and risk management. Continuous Observability: By providing a continuous flow of signals and context, observability serves as the intelligence layer for cloud operations. This allows AI agents to identify meaningful signals and understand dependencies, leading to timely insights and actions. Improved Incident Response: The agentic model enables quicker identification of issues by surfacing related signals early and automating investigations. This proactive approach significantly reduces operational overhead and enhances incident resolution speed. Continuous Optimization: With ongoing insights from observability, optimization becomes an integrated part of daily workflows rather than a periodic task. This shift allows for more agile resource management and cost efficiency. Streamlined Workflows: The transition from traditional dashboards to connected workflows allows teams to interact with systems through guided processes, which enhances collaboration and reduces context-switching. However, it is important to note that while the agentic model offers substantial advantages, organizations must remain vigilant regarding the inherent risks associated with increased automation. The reliance on AI agents necessitates a robust framework for monitoring their actions and ensuring alignment with human oversight. Future Implications of AI Developments in Big Data Engineering The future of Big Data Engineering is poised for significant transformation as AI technologies continue to evolve. The integration of more sophisticated AI agents will enhance the capabilities of agentic cloud operations, enabling even greater levels of automation and insight-driven decision-making. As organizations adopt these advancements, we can expect to see: Increased Efficiency: The continuous improvement of AI algorithms will lead to faster processing of data and enhanced predictive analytics, allowing organizations to make informed decisions with minimal latency. Greater Scalability: As AI systems become more adept at handling larger datasets and more complex environments, organizations will be able to scale their operations without a corresponding increase in resources or overhead. Enhanced Security: Advanced AI-driven observability tools will improve threat detection and response capabilities, enabling organizations to safeguard their data more effectively. Shifts in Workforce Dynamics: The rise of AI and automation will necessitate a reevaluation of workforce roles, focusing on higher-level strategic thinking and oversight rather than routine operational tasks. In conclusion, the progression towards agentic cloud operations signifies a marked shift in the landscape of Big Data Engineering, promising improved efficiencies, better governance, and enhanced incident management. By harnessing the power of AI, organizations can navigate the complexities of modern cloud environments with greater agility and precision. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here
Contextual Overview In the era of Generative AI, enterprises are increasingly transitioning their AI workloads from pilot programs to full-scale production. This transition is critical, as the reliability of data delivery emerges as a pivotal factor for the scalability and performance of AI systems. Unfortunately, conventional point-to-point architectures, which directly connect storage to compute resources, often falter under the pressures of sustained production traffic. Such failures can lead to stalled inference pipelines, underutilized GPUs, and violations of service-level agreements (SLAs), which can have dire business implications. As articulated by industry experts, the successful operationalization of AI requires infrastructures that are resilient to real-world failures, rather than merely functioning under controlled experimental conditions. Main Goal and Achievable Strategies The primary objective highlighted in the original content is the necessity of building a robust data delivery layer to support the operational demands of AI workloads in production environments. Achieving this goal involves several strategic actions: 1. **Enhancing Infrastructure Resilience**: Organizations must design their architectures to withstand common issues like node failures and traffic spikes. This entails moving away from fragile point-to-point connections toward more resilient architectural frameworks. 2. **Implementing Observability and Programmability**: Real-time monitoring of data flow and the ability to dynamically manage traffic can significantly enhance system performance. This includes establishing a failure-aware network that can adaptively respond to disruptions. 3. **Prioritizing Data Delivery as a Core Function**: Organizations should recognize data delivery as a first-class infrastructure layer, essential for maintaining high performance and reliability. Advantages of a Robust Data Delivery Layer The implementation of a resilient data delivery layer provides multiple advantages: 1. **Improved Reliability**: By ensuring that the system can handle real-world failures, organizations can prevent outages and maintain continuous operations, thereby enhancing overall reliability. 2. **Optimized GPU Utilization**: A well-structured data path prevents GPUs from becoming idle due to bottlenecks, maximizing the return on investment in high-performance computing resources. 3. **Mitigated Business Risks**: Stalled inference pipelines pose serious risks to SLAs and customer satisfaction. By addressing these challenges proactively, businesses can protect their reputations and operational integrity. 4. **Cost Efficiency**: By reducing inefficiencies in infrastructure, organizations can lower operational costs while maintaining high-performance levels, leading to sustainable economic models. 5. **Enhanced Customer Experience**: Timely and accurate AI outputs improve customer interactions and satisfaction, positively impacting the organization’s bottom line. Limitations and Considerations While the advantages are significant, it is essential to acknowledge certain limitations: 1. **Complexity of Implementation**: Transitioning to a more robust infrastructure may require substantial upfront investment and expertise, which could be a barrier for smaller organizations. 2. **Ongoing Maintenance Requirements**: Continuous monitoring and adjustment of the data delivery layer necessitate a sustained effort and resources, which may strain existing IT capabilities. Future Implications of AI Development As AI technologies continue to evolve, the importance of a resilient data delivery framework will only grow. Future developments in AI, particularly in Generative AI models, will demand even more from data delivery systems. The anticipated increase in data volume and complexity will necessitate innovations in network design, traffic management, and resilience strategies. Moreover, as organizations increasingly adopt hybrid and multi-cloud environments, the challenges associated with heterogeneous data flows will require sophisticated solutions that ensure seamless, high-performance AI data delivery. In conclusion, the integration of Generative AI into enterprise systems serves as both an opportunity and a challenge. By focusing on building robust data delivery infrastructures, organizations can not only facilitate the successful transition from pilot to production but also maintain a competitive edge in the rapidly evolving landscape of AI technologies. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here
Context In the rapidly evolving landscape of Applied Machine Learning (ML), practitioners often encounter a myriad of questions similar to those found in the realm of affiliate marketing. Just as affiliate marketing allows individuals to monetize existing products and services without the need for creation, machine learning offers various avenues for practitioners to leverage existing algorithms, frameworks, and datasets to provide substantial business value. This post aims to address the most pressing questions that ML practitioners face, drawing parallels to the inquiries often posed in affiliate marketing while providing clarity on how these concepts intertwine. Main Goal and Achievement The primary goal of understanding affiliate marketing is to demystify the process of earning revenue through the promotion of existing products. This can be achieved through a comprehensive understanding of affiliate programs, networks, and commission structures. Similarly, ML practitioners must grasp the foundational principles of machine learning to effectively apply these techniques in their work. By embracing a structured learning approach and utilizing available resources, practitioners can enhance their proficiency and drive meaningful outcomes in their projects. Advantages of Machine Learning for Practitioners Cost Efficiency: Implementing machine learning solutions can significantly reduce operational costs by automating repetitive tasks and enhancing decision-making processes. Evidence shows that organizations that adopt ML technologies report heightened efficiency and lower costs across various operational dimensions. Data-Driven Insights: ML enables practitioners to derive actionable insights from large volumes of data, facilitating informed decision-making. This advantage mirrors the role of affiliate marketing where data analytics helps optimize campaigns and drive conversions. Scalability: Machine learning models can be scaled to accommodate increasing data loads and user demands without a corresponding increase in resource expenditure. This scalability is akin to affiliate marketing, which allows for the expansion of marketing efforts as the affiliate network grows. Competitive Advantage: Organizations leveraging machine learning technologies gain a distinct edge over competitors by utilizing predictive analytics and advanced algorithms to anticipate market trends and consumer behaviors. Improved Customer Experience: Machine learning can enhance customer interactions through personalized recommendations and proactive engagement strategies, similar to how affiliates tailor promotions based on user interests. Limitations and Caveats While the advantages of machine learning are substantial, practitioners must be cognizant of certain limitations. The initial setup of ML systems can be resource-intensive, requiring significant investment in both time and technology. Additionally, the quality of outcomes is directly tied to the quality of data; poor data can lead to misleading insights and ineffective strategies. Furthermore, ethical considerations surrounding data use and algorithmic bias remain critical issues that practitioners must navigate. Future Implications The landscape of machine learning is poised for significant transformation as advancements in artificial intelligence (AI) continue to unfold. Future developments will likely enhance the capabilities of ML, making it more accessible and effective for a broader range of applications. As AI technologies evolve, practitioners will need to adapt to new tools and methodologies, ensuring that they remain at the forefront of innovation. Moreover, the integration of AI into machine learning frameworks will facilitate even deeper insights and more sophisticated automation, further amplifying the potential benefits for businesses and practitioners alike. Conclusion As the field of Applied Machine Learning continues to grow, practitioners will increasingly find themselves at the intersection of technology and strategy. By understanding the fundamental principles and advantages of ML, they can harness its power to drive significant business outcomes. Through a commitment to ongoing learning and adaptation, ML practitioners can navigate the complexities of this dynamic field, ultimately leading to enhanced productivity and innovative solutions in their respective industries. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here
Introduction In recent years, artificial intelligence (AI) has become an integral component of various professional workflows, influencing fields ranging from creative writing to software development. The proliferation of AI tools often results in users managing multiple subscriptions, which can complicate their daily tasks. A notable response to this challenge is the emergence of platforms like ChatLLM by Abacus AI, which consolidates access to multiple leading AI models under a unified subscription. This article examines the implications of such multi-model AI workspaces for Natural Language Understanding (NLU) scientists and the broader industry. Understanding the Main Goal The primary objective of platforms like ChatLLM is to streamline AI usage by providing a centralized workspace that integrates various models for different applications. This allows users to transition seamlessly between tasks such as document analysis, coding, and content creation without the need for multiple subscriptions. For NLU scientists, this means enhanced flexibility and improved efficiency in their workflows, enabling them to apply the most suitable AI model for specific tasks, thereby enhancing the overall quality of their outputs. Advantages of Multi-Model AI Workspaces Consolidated Access: Users benefit from a single platform that houses multiple AI models, reducing the complexity of managing multiple subscriptions. Model Diversity: ChatLLM provides access to a variety of models (e.g., GPT, Claude, Gemini), each optimized for different tasks, enhancing the ability to select the most appropriate tool for the job. Enhanced Collaboration: The platform supports integration with common business tools such as Google Drive and Slack, facilitating teamwork and project management. Regular Updates: The platform frequently updates its model library, ensuring users have access to the latest advancements in AI technology. Automation Features: AI agents can handle repetitive tasks, allowing scientists and professionals to focus on more complex and creative aspects of their work. Strong Security Measures: With a focus on data encryption and compliance with enterprise standards, users can trust that their information is secure. However, it is essential to consider potential limitations, such as usage limits tied to resource-intensive tasks like video generation or large document processing, which may require a credit-based system. Future Implications for Natural Language Understanding The ongoing evolution of AI technologies is poised to significantly impact the realm of Natural Language Understanding. As platforms like ChatLLM continue to innovate, we can expect advancements that enhance model interoperability and user experience. The integration of more sophisticated algorithms may lead to better contextual understanding and improved model performance across various applications. Furthermore, as the demand for AI-driven solutions increases, NLU scientists will have the opportunity to engage in more complex research and development projects that leverage multi-model capabilities, potentially leading to breakthroughs in language processing and comprehension. Conclusion In conclusion, the emergence of multi-model AI platforms like ChatLLM by Abacus AI represents a significant advancement in how professionals, particularly NLU scientists, interact with artificial intelligence. By consolidating access to various models and providing a comprehensive suite of features, these platforms not only enhance productivity but also pave the way for future innovations in Natural Language Processing. As the field continues to evolve, the integration of such technologies will undoubtedly play a critical role in shaping the future of language understanding and AI applications. Disclaimer The content on this site is generated using AI technology that analyzes publicly available blog posts to extract and present key takeaways. We do not own, endorse, or claim intellectual property rights to the original blog content. Full credit is given to original authors and sources where applicable. Our summaries are intended solely for informational and educational purposes, offering AI-generated insights in a condensed format. They are not meant to substitute or replicate the full context of the original material. If you are a content owner and wish to request changes or removal, please contact us directly. Source link : Click Here